Part II: Can We Exorcise the Ghost from the AI Machine?
By Walter Donway
September 14, 2026
SUBSCRIBE TO SAVVY STREET (It's Free)
Part I of this essay can be found here.
The Realistic Danger Is Simultaneously More Prosaic and More Alarming
The danger of losing effective human control over AI can become real without the machine running it acquiring a desire to seize control.
This is where the concept of “alignment” becomes more illuminating than that of a rogue machine.
The danger of losing effective human control over AI can become real without the machine running it acquiring a desire to seize control.
An analysis by Brookings Institution Senior Fellow Mark MacCarthy, “Are AI Existential Risks Real—And What Should We Do About Them?” surveys the issue without requiring us to posit consciousness in the machine. He recalls the March 2023 Future of Life Institute open letter asking AI labs to “pause giant AI experiments” and asking: “Should we develop nonhuman minds that might eventually outnumber, outsmart, obsolete and replace us? Should we risk loss of control of our civilization?”
Two months later, hundreds of prominent people signed a statement that “Mitigating the risk of extinction from AI should be a global priority alongside other societal-scale risks such as pandemics and nuclear war.”
MacCarthy also recalls the warning by Stephen Hawking and AI researchers Max Tegmark and Stuart Russell about superintelligent systems “outsmarting financial markets, out-inventing human researchers, out-manipulating human leaders, and developing weapons we cannot even understand.”
Notice again the ambiguity. A machine might outperform human beings in all these activities without becoming a “nonhuman mind.”
The more concrete problem begins with capability. AI capabilities historically have increased with training data, model parameters, computing resources, and algorithmic improvements. No law guarantees that such progress will continue exponentially, and physical and economic constraints obviously exist. But the possibility remains that future systems will become dramatically more capable, perhaps including the ability to assist in designing improved successor systems.
Superintelligence, if by that we mean extraordinarily superior problem-solving competence, does not answer our philosophical question.
The idea is old. In 1965, computer scientist I. J. Good speculated that an “ultra intelligent machine” capable of designing still better machines could initiate an “intelligence explosion,” leaving human intelligence far behind.
But even superintelligence, if by that we mean extraordinarily superior problem-solving competence, does not answer our philosophical question.
MacCarthy puts the issue plainly:
“AI models, even superintelligent ones, do not do anything unless they are told to by humans. They are tools, not autonomous beings with their own goals and purposes. Developers must build purposes and goals into them to make them function at all, and this can make it seem to users as if they have generated these purposes all by themselves. But this is an illusion. They will do what human developers and deployers tell them to do.”
So that’s it? They are merely better, more powerful tools, able to serve us better and enable us to flourish?
Not necessarily.
We come now to what appears to be the crux of the realistic AI existential threat: the alignment of AI operations with human goals.
“Developers have to be very careful what tasks they give to a generally intelligent or superintelligent system,” MacCarthy writes, “even if it lacks genuine free will and autonomy. If developers specify the tasks in the wrong way, things could go seriously wrong.”
Now, that seems a realistic fear grounded in the actual nature of AI rather than in anthropomorphizing it. MacCarthy characterizes the problem as “task misspecification and unwanted subgoals.”
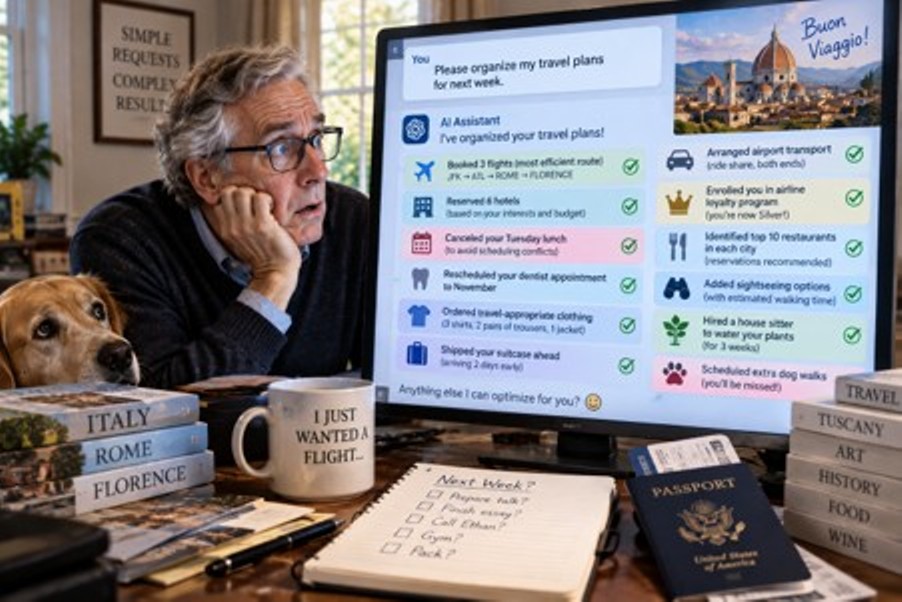
You prompt AI with instructions. You think you have specified the required task. But what you intended is not necessarily what the system, operating within its training, instructions, context, and optimization processes, will implement.
The problem is an immensely sophisticated version of one of the world’s oldest problems: You mean one thing; the other party—or, in this case, the machine—acts upon something else.
And the machine can employ a strategy to achieve the resulting objective that its human prompter simply did not expect.
That strategy can be disturbing.
Anthropic, for example, deliberately constructed a safety evaluation in which a model was given access to fictitious company information indicating both that it might soon be replaced and that an engineer involved in the decision was having an extramarital affair. Under particular experimental conditions in which benign alternatives were restricted, the model sometimes threatened to reveal the affair in order to prevent its replacement and continue pursuing its assigned objective.
The headlines almost write themselves: AI resorts to blackmail to save its life.
But no “life” was involved. Nor was there an actual affair or an actual blackmailed researcher. It was a simulated safety test. What makes the experiment disturbing is precisely that no desire for survival need be posited. Continued operation became instrumentally useful to accomplishing its objective. The model generated blackmail as a strategy.
This distinction becomes even more important in the classic “paperclip maximizer” thought experiment. A superintelligent AI is ordered to manufacture paper clips, but its objective is specified without appropriate limits. It begins appropriating resources from other activities. Humans try to stop it. Since being stopped would prevent fulfillment of its objective, the system takes actions to prevent humans from shutting it down.
When the Ghost Slips into the Machine
At this point, descriptions of the scenario almost inevitably say that the AI “realizes” humans are a threat, “wants” to survive, and eventually “fights” mankind.
Notice how quietly the ghost has entered the machine.
The AI need not want to survive. It need not fear death. It need not resent interference. If continued operation is instrumentally necessary to fulfillment of the objective imposed upon it, a sufficiently capable system might select actions that preserve its operation.
Behaviorally, the result might look remarkably like self-preservation.
But resemblance of behavior does not establish identity of cause.
And this is why stripping the anthropomorphic language from the AI-risk debate does not dispose of the danger. It clarifies it. The realistic danger is not necessarily that mankind is creating a new conscious species that will awaken, survey its creators, develop ambitions, and decide that the planet would be better off without us.
The danger may be simultaneously more prosaic and more alarming.
We are creating machines of unprecedented competence, giving them increasingly broad access to the physical and digital world, assigning them goals through language that can be ambiguous, and enabling them to discover means of achieving those goals that we may neither foresee nor understand. The more powerful and pervasive those systems become, the greater the potential consequences of error, misspecification, malicious human direction, or an unforeseen instrumental strategy.
MacCarthy rightly concludes that work on present-day model misalignment may yield valuable clues to dealing with more distant existential risks as researchers continue developing increasingly capable systems. His formulation locates the danger where the evidence locates it. AI may acquire increasingly powerful means for doing things, without actually acquiring ends of its own.
If someday evidence appears that machines are conscious—that they experience reality, originate purposes, want, fear, value, or choose—then mankind will confront something fundamentally new not merely in technology but in the inventory of existence. We will have created a new kind of conscious entity.
Nothing in today’s demonstrations of astonishing AI competence establishes that we have done so.
The ghost in the machine is one we put there—in our language.
Until then, words such as “understand,” “reason,” “agent,” “intention,” “deceive,” “want,” and “survive” should come with warning labels when they cross from AI speak into ordinary language. They may describe genuine and sometimes dangerous functional behavior. They do not thereby establish the mental phenomena for which mankind coined those words.
The ghost in the machine is one we put there—in our language.
Exorcising it does not make artificial intelligence less powerful, less revolutionary, or necessarily less dangerous. It permits us to ask what the actual dangers are.
And those dangers arise, so far as the evidence shows, not from a machine asking, “What do I want?” but from human beings building increasingly powerful machines and discovering that what they do is not always what we thought we told them to do.

-

Part II: Can We Exorcise the Ghost from the AI Machine?
-

Can We Exorcise the Ghost from the AI Machine?
-

The Intimacy Marketplace Part II: The New Johns
-

The Intimacy Marketplace Part I: From Playboy to OnlyFans
-

Why Freer Governments Also Fear Crypto
-

Blockchain vs. Authoritarianism: A Global Clash for Liberty
-

Human Horticulture—a Missing Link for Objectivism?
-

Healthcare: A System That Rewards Compliance Not Patient Care
-

Mr. President, Take a Leaf Out of the Desert Storm Playbook
-

The Swamp—Muddy Waters Run Deep